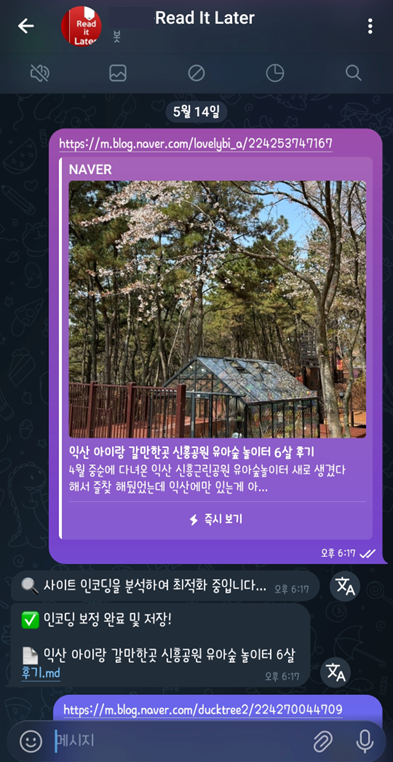
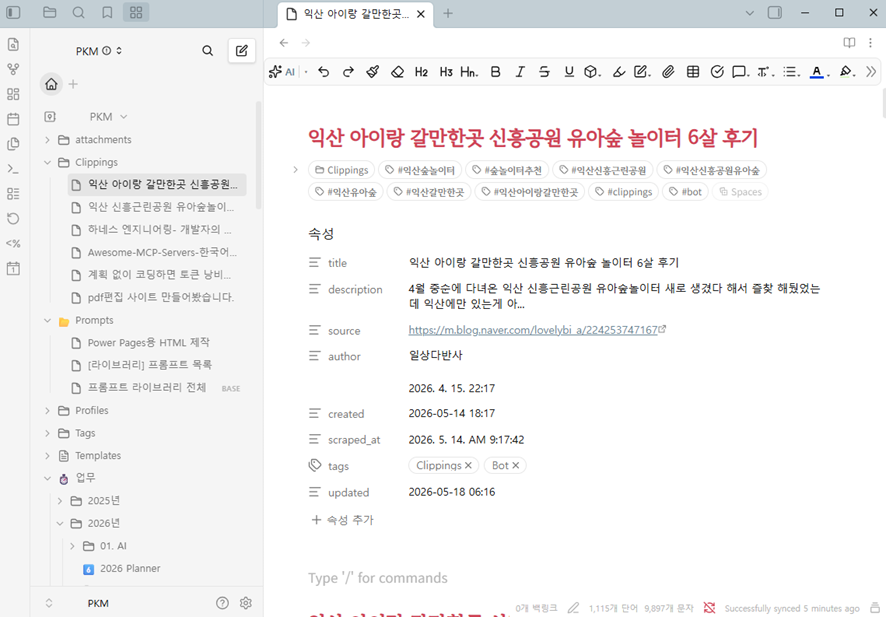
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
200
201
202
203
204
205
206
207
208
209
210
211
212
213
214
215
216
217
218
219
220
221
222
223
224
225
226
227
228
229
230
231
232
233
234
235
236
237
238
239
240
241
242
243
244
245
246
247
248
249
250
251
252
253
254
255
256
257
258
259
260
261
262
263
264
265
266
267
268
269
270
271
272
273
274
275
276
277
278
279
280
281
282
283
284
285
286
287
288
289
290
291
292
293
294
295
296
297
298
299
300
301
302
303
304
305
306
307
308
309
310
311
312
313
314
315
316
317
318
319
320
321
322
323
324
325
326
327
328
329
330
331
332
333
334
335
336
337
338
339
340
341
342
343
344
345
346
347
348
349
350
351
352
353
354
355
356
357
358
359
360
361
362
363
364
365
366
367
368
369
370
371
372
373
374
375
376
377
378
379
380
381
382
383
384
385
386
387
388
389
390
391
392
393
394
395
396
397
398
399
400
401
402
403
404
405
406
407
408
409
410
411
412
413
414
415
416
417
418
419
420
421
422
423
424
425
426
427
428
429
430
431
432
433
434
435
436
437
438
439
440
441
442
443
444
445
446
447
448
449
450
451
452
453
454
455
456
457
458
459
460
461
462
463
464
465
466
467
468
469
470
471
472
473
474
475
476
477
478
479
480
481
482
483
484
485
486
487
488
489
490
491
492
493
494
495
496
497
498
499
500
501
502
503
504
505
506
507
508
509
510
511
512
513
514
515
516
517
518
519
520
521
522
523
524
525
526
527
528
529
530
531
532
533
534
535
536
537
538
539
540
541
542
543
544
545
546
547
548
549
550
551
552
553
554
555
556
557
558
559
560
561
562
563
564
565
566
567
568
569
570
571
572
573
574
575
576
577
578
579
580
581
582
583
584
585
586
587
588
589
590
591
592
593
594
595
596
597
598
599
600
601
602
603
604
605
606
607
608
609
610
611
612
613
614
615
616
617
618
619
620
621
622
623
624
625
626
627
628
629
630
631
632
633
634
635
636
637
638
639
640
641
642
643
644
645
646
647
648
649
650
651
652
653
654
655
656
657
658
659
660
661
662
663
664
| import { NextRequest, NextResponse } from 'next/server';
import { Readability } from '@mozilla/readability';
import { JSDOM } from 'jsdom';
// @ts-ignore
import TurndownService from 'turndown';
import { createClient } from 'webdav';
import iconv from 'iconv-lite';
const TELEGRAM_TOKEN = process.env.TELEGRAM_TOKEN;
const KOOFR_EMAIL = process.env.KOOFR_EMAIL;
const KOOFR_APP_PASSWORD = process.env.KOOFR_APP_PASSWORD;
const ALLOWED_USER_ID = process.env.ALLOWED_USER_ID;
const KOOFR_WEBDAV_URL = 'https://app.koofr.net/dav/Koofr';
// jsdom, iconv-lite, webdav는 Node.js API를 사용하므로 Edge Runtime을 사용하지 않는다.
export const runtime = 'nodejs';
// Netlify/Vercel 등에서 지원하는 플랫폼이라면 함수 실행 제한 시간을 늘려본다.
// (플랫폼/플랜에 따라 무시될 수 있음 — 실제 제한은 호스팅 콘솔에서 확인 필요)
export const maxDuration = 60;
const DESKTOP_USER_AGENT =
'Mozilla/5.0 (Windows NT 10.0; Win64; x64) ' +
'AppleWebKit/537.36 (KHTML, like Gecko) Chrome/122.0.0.0 Safari/537.36';
const MOBILE_USER_AGENT =
'Mozilla/5.0 (iPhone; CPU iPhone OS 17_4 like Mac OS X) ' +
'AppleWebKit/605.1.15 (KHTML, like Gecko) Version/17.4 Mobile/15E148 Safari/604.1';
const FETCH_TIMEOUT_MS = 20_000;
// 봇 차단/비정상 접근 안내 페이지에서 흔히 쓰이는 문구.
// HTTP 200이 와도 실제로는 차단 페이지인 경우를 잡아내기 위한 용도.
const BLOCK_PAGE_HINTS = [
'비정상적인 접근',
'자동화된 접근',
'접근이 제한',
'정상적인 경로로 접속',
'로봇이 아닙니다',
'captcha',
'Access Denied',
'Attention Required',
];
/**
* m. 서브도메인 등 모바일 전용 페이지는 모바일 UA로 접근해야
* 정상적인 모바일 레이아웃(및 본문)을 받을 확률이 높다.
* 데스크톱 UA로 접근하면 "PC로 접속해주세요" 같은 안내 페이지만 오는 경우가 있다.
*/
function pickUserAgent(hostname: string): string {
return /^m\.|\.m\.|^mobile\./i.test(hostname) ? MOBILE_USER_AGENT : DESKTOP_USER_AGENT;
}
function looksLikeBlockPage(sampleHtml: string): boolean {
return BLOCK_PAGE_HINTS.some(hint => sampleHtml.includes(hint));
}
async function fetchWithTimeout(
url: string,
headers: Record<string, string>,
timeoutMs = FETCH_TIMEOUT_MS,
): Promise<Response> {
const controller = new AbortController();
const timer = setTimeout(() => controller.abort(), timeoutMs);
try {
return await fetch(url, { redirect: 'follow', headers, signal: controller.signal });
} finally {
clearTimeout(timer);
}
}
type FetchResult = { buffer: Buffer; contentType: string | null; finalUrl: string };
/**
* 동일 URL에 대해 UA/Referer 조합을 바꿔가며 최대 2회 시도한다.
* - 1차 시도: 호스트에 맞는 UA(m.* 이면 모바일 UA) + 구글 리퍼러
* - 2차 시도: 반대쪽 UA + 자기 사이트 리퍼러 + (1차에서 받은 쿠키가 있으면 함께 전송)
* 응답이 비정상적으로 짧거나 "차단 안내" 문구가 보이면 실패로 간주하고 다음 시도로 넘어간다.
* 두 시도 모두 실패하면 마지막 에러를 던진다 — 상위에서 사용자에게 구체적인 원인을 보여줄 수 있게 한다.
*/
async function fetchWithRetry(url: string): Promise<FetchResult> {
let hostname = '';
try {
hostname = new URL(url).hostname;
} catch {
// no-op
}
const attempts: Array<{ ua: string; referer: string }> = [
{ ua: pickUserAgent(hostname), referer: 'https://www.google.com/' },
{
ua: hostname.startsWith('m.') ? DESKTOP_USER_AGENT : MOBILE_USER_AGENT,
referer: hostname ? `https://${hostname}/` : 'https://www.google.com/',
},
];
let lastError: unknown = new Error('알 수 없는 오류로 모든 시도가 실패했습니다.');
let carriedCookie: string | undefined;
for (const attempt of attempts) {
try {
const headers: Record<string, string> = {
'User-Agent': attempt.ua,
Accept: 'text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8',
'Accept-Language': 'ko-KR,ko;q=0.9,en-US;q=0.7,en;q=0.5',
'Accept-Encoding': 'gzip, deflate, br',
Referer: attempt.referer,
Connection: 'keep-alive',
'Upgrade-Insecure-Requests': '1',
'Sec-Fetch-Dest': 'document',
'Sec-Fetch-Mode': 'navigate',
'Sec-Fetch-Site': 'same-origin',
'Sec-Fetch-User': '?1',
};
if (carriedCookie) headers['Cookie'] = carriedCookie;
const response = await fetchWithTimeout(url, headers);
const setCookie = response.headers.get('set-cookie');
if (setCookie) carriedCookie = setCookie;
if (!response.ok) {
lastError = new Error(`HTTP ${response.status} ${response.statusText} (요청: ${url})`);
continue;
}
const contentType = response.headers.get('content-type');
const buffer = Buffer.from(await response.arrayBuffer());
const finalUrl = response.url || url;
if (buffer.length < 500) {
lastError = new Error('응답 본문이 비정상적으로 짧습니다 (차단/오류 페이지로 추정).');
continue;
}
const sample = buffer.subarray(0, 8000).toString('utf-8');
if (looksLikeBlockPage(sample)) {
lastError = new Error('사이트가 비정상 접근으로 판단해 차단 페이지를 반환한 것으로 보입니다.');
continue;
}
return { buffer, contentType, finalUrl };
} catch (error) {
lastError =
error instanceof Error && error.name === 'AbortError'
? new Error(`요청 시간 초과 (${FETCH_TIMEOUT_MS}ms, 요청: ${url})`)
: error;
}
}
throw lastError;
}
/**
* 직접 요청이 계속 403/차단으로 막히는 사이트(예: 뽐뿌)를 위한 최후 수단.
* ppomppu 같은 곳은 UA/Referer를 바꿔도 뚫리지 않는 경우가 많은데, 이는 헤더 문제가
* 아니라 서버리스(클라우드) IP 대역 자체를 차단하는 WAF 정책일 가능성이 높다.
* r.jina.ai는 자체 크롤러가 대신 페이지를 가져와 정제된 마크다운으로 반환해주는
* 무료 공개 서비스라, 우리 서버 IP가 차단당해도 우회할 수 있다.
* (단, jina 쪽도 대상 사이트로부터 언젠가 막힐 수는 있다 — 100% 보장은 아님)
*/
async function fetchViaJinaReader(url: string): Promise<{ title: string; markdown: string } | null> {
try {
const readerUrl = `https://r.jina.ai/${url}`;
const response = await fetchWithTimeout(
readerUrl,
{
Accept: 'text/plain',
'X-Return-Format': 'markdown',
},
25_000,
);
if (!response.ok) return null;
const text = await response.text();
if (!text || text.trim().length < 200) return null;
const titleMatch = text.match(/^Title:\s*(.+)$/m);
const markdownStart = text.search(/^Markdown Content:/m);
const markdown =
markdownStart >= 0
? text.slice(markdownStart).replace(/^Markdown Content:\s*/, '')
: text;
return {
title: normalizeText(titleMatch?.[1]),
markdown: markdown.trim(),
};
} catch (error) {
console.error('Jina reader fallback failed:', error);
return null;
}
}
/**
* HTML 앞부분은 charset 선언 자체가 ASCII이므로 latin1로 읽어도 안전하다.
* meta charset과 과거형 http-equiv/content 선언을 모두 지원한다.
*/
function getDeclaredCharset(buffer: Buffer, contentType: string | null): string | null {
const headerMatch = contentType?.match(/charset\s*=\s*["']?([^\s;"']+)/i);
if (headerMatch) return headerMatch[1].toLowerCase();
const head = buffer.subarray(0, 64 * 1024).toString('latin1');
const metaCharset = head.match(/<meta\b[^>]*\bcharset\s*=\s*["']?([^\s"'/>;]+)/i);
if (metaCharset) return metaCharset[1].toLowerCase();
const httpEquiv = head.match(
/<meta\b[^>]*\bcontent\s*=\s*["'][^"']*charset\s*=\s*([^\s;"']+)[^"']*["'][^>]*>/i,
);
return httpEquiv?.[1]?.toLowerCase() ?? null;
}
function normalizeCharset(charset: string | null): string | null {
if (!charset) return null;
const value = charset.trim().toLowerCase().replace(/["']/g, '');
if (['utf-8', 'utf8'].includes(value)) return 'utf-8';
if (
value.includes('euc-kr') ||
value.includes('cp949') ||
value.includes('ms949') ||
value.includes('x-windows-949') ||
value.includes('ks_c_5601') ||
value.includes('ks-c-5601')
) {
// CP949는 EUC-KR의 확장 문자까지 포함하므로 국내 레거시 사이트에 더 안전하다.
return 'cp949';
}
return iconv.encodingExists(value) ? value : null;
}
function isValidUtf8(buffer: Buffer): boolean {
try {
new TextDecoder('utf-8', { fatal: true }).decode(buffer);
return true;
} catch {
return false;
}
}
function countBrokenCharacters(value: string): number {
return (
(value.match(/\uFFFD/g) || []).length +
(value.match(/[\u0000-\u0008\u000B\u000C\u000E-\u001F]/g) || []).length
);
}
/**
* 최신 네이버처럼 선언값과 실제 바이트가 어긋나는 경우를 막기 위해
* 유효한 UTF-8 바이트는 UTF-8을 최우선으로 사용한다.
* UTF-8이 아니면 선언 인코딩과 CP949 후보 중 손상 문자가 적은 결과를 택한다.
*/
function decodeHtml(buffer: Buffer, contentType: string | null): string {
// UTF-8 BOM
if (buffer.length >= 3 && buffer[0] === 0xef && buffer[1] === 0xbb && buffer[2] === 0xbf) {
return iconv.decode(buffer, 'utf-8');
}
if (isValidUtf8(buffer)) return iconv.decode(buffer, 'utf-8');
const declared = normalizeCharset(getDeclaredCharset(buffer, contentType));
const encodings = Array.from(new Set([declared, 'cp949'].filter(Boolean))) as string[];
const candidates = encodings.map(encoding => ({
encoding,
html: iconv.decode(buffer, encoding),
}));
candidates.sort((a, b) => countBrokenCharacters(a.html) - countBrokenCharacters(b.html));
return candidates[0]?.html ?? iconv.decode(buffer, 'utf-8');
}
function normalizeText(value: string | null | undefined): string {
return (value || '')
.normalize('NFC')
.replace(/\uFFFD+/g, '')
.replace(/[\u0000-\u001F\u007F]/g, ' ')
.replace(/\s+/g, ' ')
.trim();
}
function yamlString(value: string): string {
return JSON.stringify(normalizeText(value));
}
function makeSafeFileName(title: string): string {
// 네이버 블로그 제목은 글자 수/문자 제한이 없어서 국기 이모지(🇸🇬 같은 것도 실제로는
// 코드포인트 2개가 결합된 특수 문자), 《》 같은 특수 괄호, 기타 심볼이 자유롭게
// 들어간다. 이런 문자들은 WebDAV 경로에서 깨지거나 서버가 처리하지 못해 404를
// 유발할 수 있으므로, 화이트리스트 방식(글자/숫자/공백/기본 문장부호만 허용)으로
// 한 글자씩 걸러낸다 — 알려진 위험 문자만 골라서 막는 것보다 훨씬 안전하다.
const ALLOWED_PUNCTUATION = new Set([
'-', '_', '.', ',', '(', ')', '[', ']', '!', '?', '~', "'",
]);
const normalized = normalizeText(title);
let cleaned = '';
for (const ch of normalized) {
// \p{L}: 모든 언어의 글자, \p{N}: 숫자, \p{Zs}: 공백류
if (/[\p{L}\p{N}\p{Zs}]/u.test(ch) || ALLOWED_PUNCTUATION.has(ch)) {
cleaned += ch;
} else {
// 이모지(국기 포함), 《》 등 특수 괄호, 기타 심볼은 전부 하이픈으로.
cleaned += '-';
}
}
cleaned = cleaned
// 화이트리스트를 통과했더라도 경로/URL에서 특별한 의미를 가지는 문자는
// 한 번 더 확실하게 걸러낸다 (' 나 ( ) 등은 남기되, 실제 구분자 역할을 하는 것만).
.replace(/[\\/:*?"<>|%#&+;@=]/g, '-')
.replace(/-{2,}/g, '-')
.replace(/\.+$/g, '')
.replace(/\s+/g, ' ')
.trim()
.slice(0, 150);
return `${cleaned || 'Untitled'}.md`;
}
/**
* Koofr(WebDAV) 업로드. 파일명에 sanitize로 걸러내지 못한 문자가 남아 있거나
* 그 외 이유로 PUT이 실패하면, 타임스탬프 기반의 확실히 안전한 이름으로
* 한 번 더 시도해서 최소한 내용은 보존한다.
*/
async function uploadToKoofr(
client: ReturnType<typeof createClient>,
fileName: string,
content: string,
): Promise<string> {
try {
await client.putFileContents(`/ReadItLater/${fileName}`, content, {
overwrite: true,
});
return fileName;
} catch (error) {
console.error(`Koofr upload failed for "${fileName}", retrying with safe name:`, error);
const fallbackName = `Clip-${Date.now()}.md`;
await client.putFileContents(`/MiNi_PKM/Clippings/${fallbackName}`, content, {
overwrite: true,
});
return fallbackName;
}
}
/**
* 네이버 블로그/카페 PC 버전은 실제 본문이 iframe(예: iframe#mainFrame)으로
* 별도 URL에서 로드된다. m. 서브도메인이 아닌 경우에만 시도한다.
*/
function findMainIframeSrc(document: Document, baseUrl: string): string | null {
let host = '';
try {
host = new URL(baseUrl).hostname;
} catch {
return null;
}
if (!/(^|\.)naver\.com$/.test(host) || host.startsWith('m.')) return null;
const iframe =
document.querySelector('iframe#mainFrame') ||
document.querySelector('iframe#cafe_main') ||
document.querySelector('iframe[name="mainFrame"]');
const src = iframe?.getAttribute('src');
if (!src) return null;
try {
return new URL(src, baseUrl).href;
} catch {
return null;
}
}
/**
* Readability가 실패하거나 텍스트가 거의 없는데 원본에는 이미지가 많은 경우
* (뽐뿌처럼 이미지 위주 게시물에서 자주 발생) 대비용 대체 추출기.
* 광고/댓글/네비게이션성 클래스명을 제외하고, 이미지 수 + 텍스트 길이 기준으로
* 가장 "본문 같은" 블록을 고른다. 정교하지는 않지만 Readability가 완전히
* 빈 손으로 돌아오는 것보다는 낫다.
*/
function pickBestContentBlock(document: Document): Element | null {
const EXCLUDE_CLASS_HINTS =
/(ad|banner|comment|reply|sidebar|related|footer|header|^nav$|snb|gnb|share|copyright)/i;
const candidates = Array.from(document.querySelectorAll('div, td, article, section, main'));
let best: Element | null = null;
let bestScore = 0;
for (const el of candidates) {
const cls = (el.className || '').toString();
if (EXCLUDE_CLASS_HINTS.test(cls)) continue;
const imgCount = el.querySelectorAll('img').length;
const textLen = normalizeText(el.textContent).length;
const score = imgCount * 200 + textLen;
if (score > bestScore && (imgCount > 0 || textLen > 100)) {
bestScore = score;
best = el;
}
}
return best;
}
type ExtractedArticle = { title: string; content: string; excerpt: string; byline: string };
/**
* Readability를 우선 시도하되, 텍스트 임계값을 낮춰 이미지 위주 게시물도
* 통과할 확률을 높인다. 결과가 비어있거나 지나치게 부실하면(원본엔 이미지가
* 있는데 추출 결과엔 없는 경우 등) pickBestContentBlock으로 대체한다.
*/
function extractArticle(document: Document): ExtractedArticle | null {
let article: ReturnType<Readability['parse']> = null;
try {
// Readability는 전달받은 document를 변형하므로, 대체 추출을 위해
// 원본은 그대로 두고 클론에 대해 파싱한다.
const clone = document.cloneNode(true) as Document;
article = new Readability(clone, { charThreshold: 120 }).parse();
} catch (error) {
console.error('Readability parse error:', error);
}
const readabilityText = normalizeText(article?.textContent);
const readabilityImgCount = article?.content ? (article.content.match(/<img/gi) || []).length : 0;
const rawImgCount = document.querySelectorAll('img').length;
const readabilityLooksWeak =
!article?.content || (readabilityText.length < 80 && readabilityImgCount === 0 && rawImgCount > 0);
if (readabilityLooksWeak) {
const fallbackEl = pickBestContentBlock(document);
if (fallbackEl) {
return {
title: normalizeText(article?.title),
content: fallbackEl.innerHTML,
excerpt: normalizeText(fallbackEl.textContent).slice(0, 200),
byline: normalizeText(article?.byline),
};
}
}
if (!article?.content) return null;
return {
title: normalizeText(article.title),
content: article.content,
excerpt: normalizeText(article.excerpt),
byline: normalizeText(article.byline),
};
}
export async function POST(req: NextRequest) {
try {
const body = await req.json();
const message = body.message;
if (!message?.text) return NextResponse.json({ ok: true });
const chatId = message.chat.id;
if (ALLOWED_USER_ID && String(chatId) !== String(ALLOWED_USER_ID)) {
return NextResponse.json({ ok: true });
}
const urlMatch = message.text.match(/https?:\/\/[^\s]+/g);
if (!urlMatch) return NextResponse.json({ ok: true });
let targetUrl = urlMatch[0];
try {
const urlObj = new URL(targetUrl);
['utm_source', 'utm_medium', 'utm_campaign', 'ref'].forEach(param =>
urlObj.searchParams.delete(param),
);
targetUrl = urlObj.toString();
} catch {
// URL 생성 실패 시 Telegram에서 추출한 원문을 그대로 사용한다.
}
await sendTelegramMessage(chatId, '🔍 원본 콘텐츠 및 고화질 이미지 분석 중...');
let title = 'Untitled';
let markdownContent = '';
let description = '';
let author = 'Unknown';
let effectiveUrl = targetUrl;
let primaryError: unknown = null;
try {
const initial = await fetchWithRetry(targetUrl);
let html = decodeHtml(initial.buffer, initial.contentType);
effectiveUrl = initial.finalUrl;
let dom = new JSDOM(html, { url: effectiveUrl });
let document = dom.window.document;
// 네이버 블로그/카페 PC 버전처럼 실제 본문이 iframe에 있는 경우, 그 iframe을 따라가서
// 실제 콘텐츠 페이지를 다시 받아온다.
const hopUrl = findMainIframeSrc(document, effectiveUrl);
if (hopUrl) {
try {
const hop = await fetchWithRetry(hopUrl);
html = decodeHtml(hop.buffer, hop.contentType);
effectiveUrl = hop.finalUrl;
dom = new JSDOM(html, { url: effectiveUrl });
document = dom.window.document;
} catch (hopError) {
// iframe 후속 요청이 실패해도 원본 문서로 계속 시도해본다.
console.error('iframe hop fetch failed:', hopError);
}
}
// Readability가 DOM을 변경하기 전에 신뢰도 높은 제목 후보를 보관한다.
const ogTitle = normalizeText(
document.querySelector('meta[property="og:title"]')?.getAttribute('content'),
);
const originalDocumentTitle = normalizeText(document.title);
['script', 'style', 'noscript', 'footer', 'nav'].forEach(selector => {
document.querySelectorAll(selector).forEach(element => element.remove());
});
// 본문 iframe을 무조건 제거하면 일부 네이버 카페 페이지의 실제 글도 사라질 수 있다.
// 광고/추적용 iframe만 제거하고, 같은 네이버 계열 iframe은 남긴다.
document.querySelectorAll('iframe').forEach(iframe => {
const src = iframe.getAttribute('src') || '';
let keep = false;
try {
const host = new URL(src, effectiveUrl).hostname;
keep = host === 'naver.com' || host.endsWith('.naver.com');
} catch {
keep = false;
}
if (!keep) iframe.remove();
});
document.querySelectorAll('a').forEach(anchor => {
const href = anchor.getAttribute('href');
if (!href || href === '#' || anchor.querySelector('img')) {
anchor.replaceWith(...Array.from(anchor.childNodes));
}
});
const article = extractArticle(document);
if (!article?.content) {
throw new Error('본문을 추출할 수 없습니다 (Readability 및 대체 추출 모두 실패).');
}
title = ogTitle || article.title || originalDocumentTitle || 'Untitled';
const turndownService = new TurndownService({
headingStyle: 'atx',
hr: '---',
bulletListMarker: '-',
codeBlockStyle: 'fenced',
});
turndownService.addRule('absoluteImages', {
filter: 'img',
replacement: function (_content, node: any) {
const src =
node.getAttribute('data-lazy-src') ||
node.getAttribute('data-source') ||
node.getAttribute('data-src') ||
node.getAttribute('src');
if (!src) return '';
try {
let absoluteUrl = new URL(src.split(' ')[0], effectiveUrl).href;
if (absoluteUrl.includes('pstatic.net') || absoluteUrl.includes('blogfiles')) {
const cleanUrl = new URL(absoluteUrl);
if (cleanUrl.searchParams.has('type')) cleanUrl.searchParams.set('type', 'w1');
absoluteUrl = cleanUrl.toString();
}
const alt = normalizeText(node.getAttribute('alt')) || 'image';
return `\n\n`;
} catch {
return '';
}
},
});
markdownContent = turndownService.turndown(article.content);
description = article.excerpt;
author = article.byline || 'Unknown';
} catch (error) {
// 직접 접근이 막히거나(403 등) 본문 추출에 실패한 경우, 여기서 바로 실패
// 처리하지 않고 Jina Reader 우회 경로를 마지막으로 한 번 더 시도해본다.
primaryError = error;
console.error('Primary scrape failed, trying Jina reader fallback:', error);
const jina = await fetchViaJinaReader(targetUrl);
if (!jina || !jina.markdown) {
const detail = primaryError instanceof Error ? primaryError.message : String(primaryError);
await sendTelegramMessage(
chatId,
`❌ 처리 중 에러가 발생했습니다.\n\n원인: ${detail.slice(0, 300)}\n(대체 경로(Jina Reader) 시도도 실패)`,
);
return NextResponse.json({ ok: true });
}
title = jina.title || title;
markdownContent = jina.markdown;
description = '';
author = 'Unknown';
}
try {
const now = new Date();
const frontmatter = `---
title: ${yamlString(title)}
description: ${yamlString(description)}
source: ${yamlString(effectiveUrl)}
author: ${yamlString(author)}
created: ${now.toISOString().split('T')[0]}
scraped_at: ${yamlString(now.toLocaleString('ko-KR', { timeZone: 'Asia/Seoul' }))}
tags: ["ReadItLater"]
---
`;
const finalContent = `${frontmatter}# ${title}\n\n${markdownContent}`;
const fileName = makeSafeFileName(title);
const client = createClient(KOOFR_WEBDAV_URL, {
username: KOOFR_EMAIL,
password: KOOFR_APP_PASSWORD,
});
const savedFileName = await uploadToKoofr(client, fileName, finalContent);
await sendTelegramMessage(chatId, `✅ 아카이빙 완료!\n\n📄 ${savedFileName}`, true);
} catch (error) {
console.error('Upload error:', error);
const detail = error instanceof Error ? error.message : String(error);
await sendTelegramMessage(
chatId,
`❌ 저장 중 에러가 발생했습니다.\n\n원인: ${detail.slice(0, 300)}`,
);
}
return NextResponse.json({ ok: true });
} catch (error) {
console.error('Webhook error:', error);
return NextResponse.json({ ok: false }, { status: 500 });
}
}
async function sendTelegramMessage(chatId: number, text: string, disablePreview = false) {
const url = `https://api.telegram.org/bot${TELEGRAM_TOKEN}/sendMessage`;
await fetch(url, {
method: 'POST',
headers: { 'Content-Type': 'application/json' },
body: JSON.stringify({
chat_id: chatId,
text,
disable_web_page_preview: disablePreview,
}),
});
}
|